
SOLUTION //
Veeam Operator
Re-running a failed Veeam job only helps when the cause was temporary. How 2501 finds why each machine failed, retries only when it should, and reports real restore points.

TICKETS FROM
ServiceNow or another ITSM
SAFEGUARDS
Your rules, confirmation and blacklists
AUTONOMY
Investigate only, with a person, or on its own
DEPLOYMENT
On-prem, cloud or hybrid
█
SOLUTION_BRIEFING
// HOW 2501 HANDLES IT
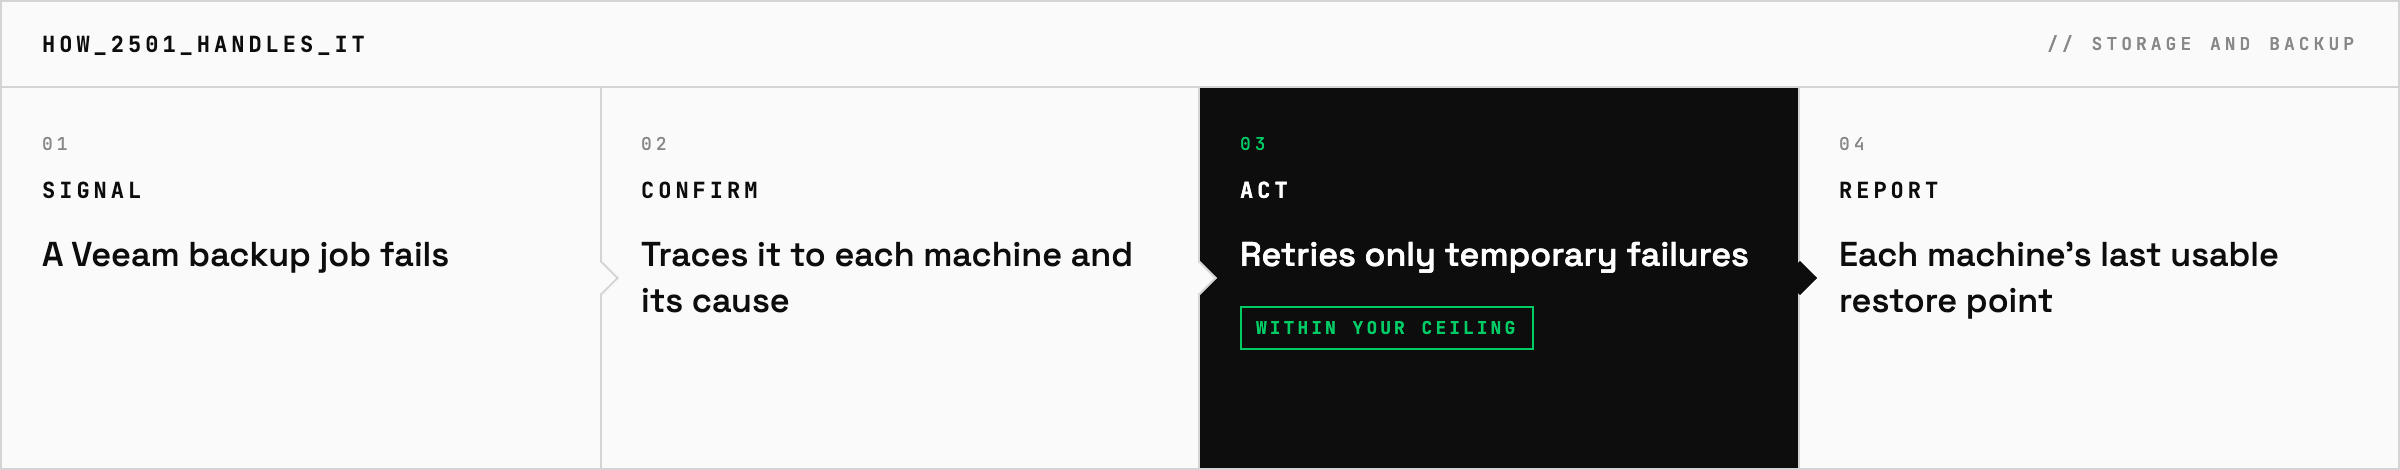
When a Veeam backup job fails, re-running it is the reflex, but unless the cause was temporary it fails the same way again, while its machines go on without a usable restore point. 2501 finds out why each machine failed, retries only when the cause is temporary, and reports how recoverable each machine really is.
The job's status says little on its own. What matters is which machines have no usable restore point, and for how long.
The Veeam specialty takes the alert from your ticketing system and traces the failed job to the machines behind it, since one failing machine can fail a whole job. For each one it names the cause, such as expired credentials, a full or unreachable repository, an application that could not be captured consistently, or a licence problem. It retries only temporary failures, never stacks retries, and escalates a failure that keeps coming back.
Its report gives each machine's real recovery point, its last usable restore point, and flags gaps in backup chains and repositories running short of space.
Can a job succeed and still leave a machine unprotected? Yes. Where Veeam tests that backups can really be restored, 2501 treats those results as the stronger signal and flags jobs that passed but failed the test.
Does it handle machines on VMware and Hyper-V? Yes. It diagnoses failures on both, including snapshots the hypervisor is slow to remove after a backup.
> READY_TO_DEPLOY
Book a technical demo and walk through your own environment with the 2501 team.
