
SOLUTION //
Google Cloud Central
A Compute Engine instance stops answering and the quick fixes are blunt ones. How 2501 finds where the connection fails and makes the most precise fix, within your limits.
TICKETS FROM
ServiceNow or another ITSM
SAFEGUARDS
Your rules, confirmation and blacklists
AUTONOMY
Investigate only, with a person, or on its own
DEPLOYMENT
On-prem, cloud or hybrid
█
SOLUTION_BRIEFING
// HOW 2501 HANDLES IT
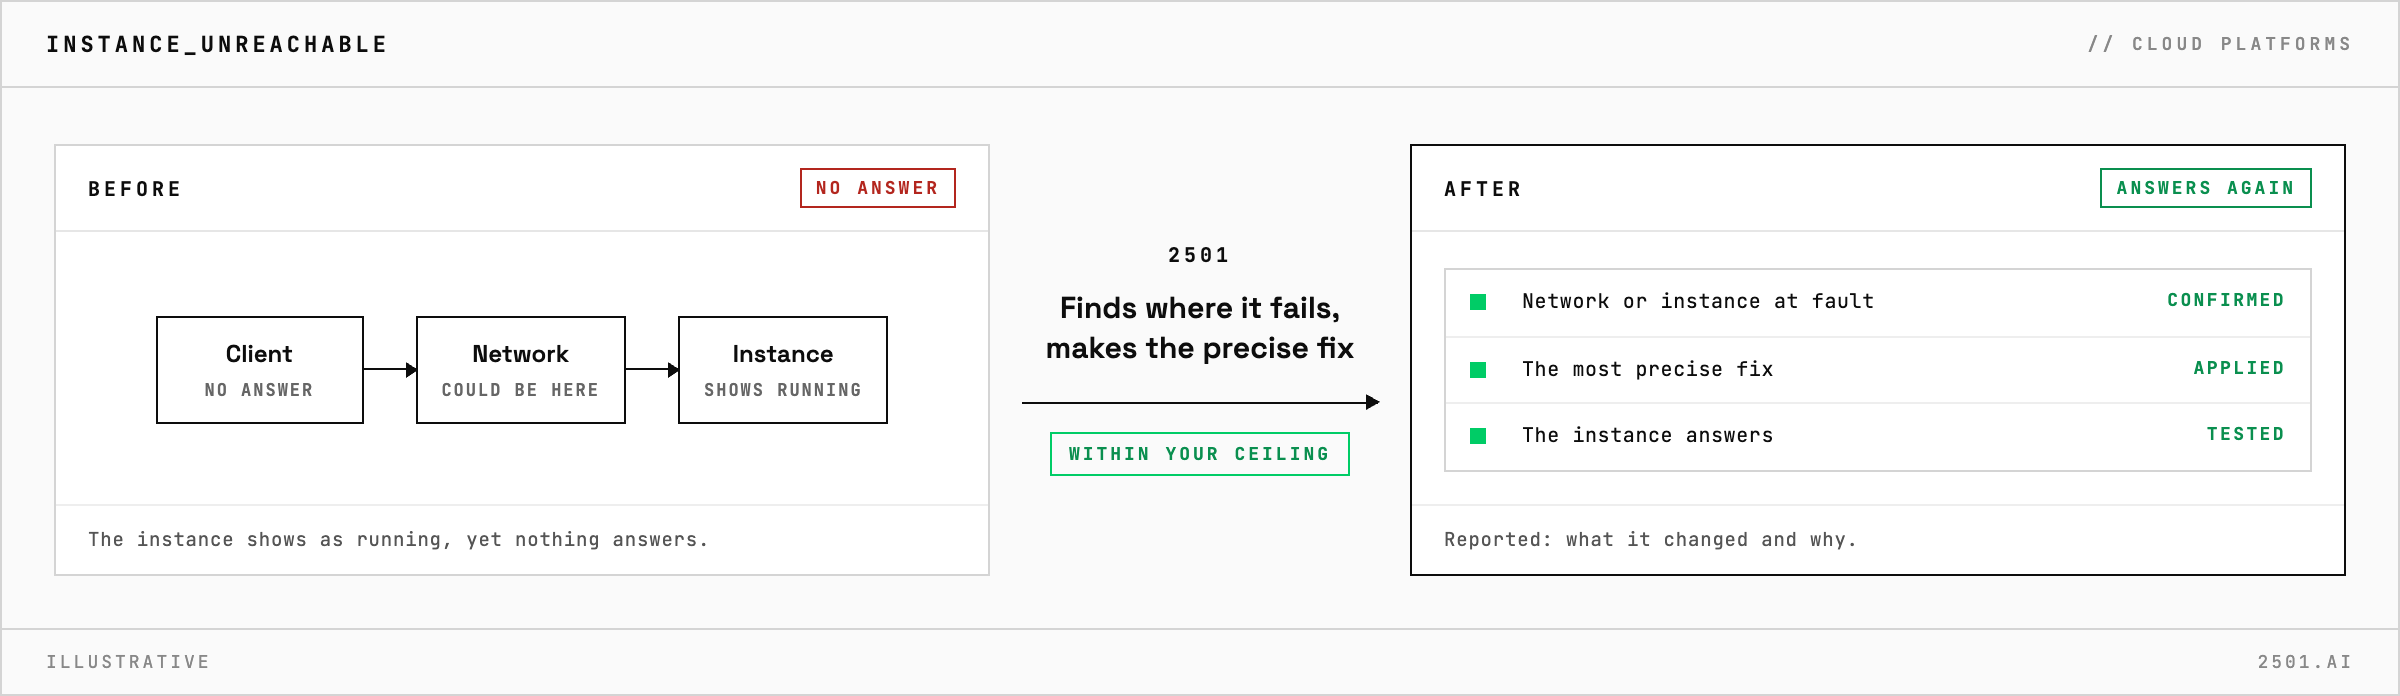
When a Compute Engine instance cannot be reached, the quick fixes are blunt: a reset restarts it without a clean shutdown, and a wider firewall rule lets in far more than the connection you needed. 2501 finds where the connection fails and makes the most precise fix that restores it, all within limits you set.
The instance shows as running, yet nothing answers. The cause can sit in the network in front of it or in the instance itself, and from outside the two look the same.
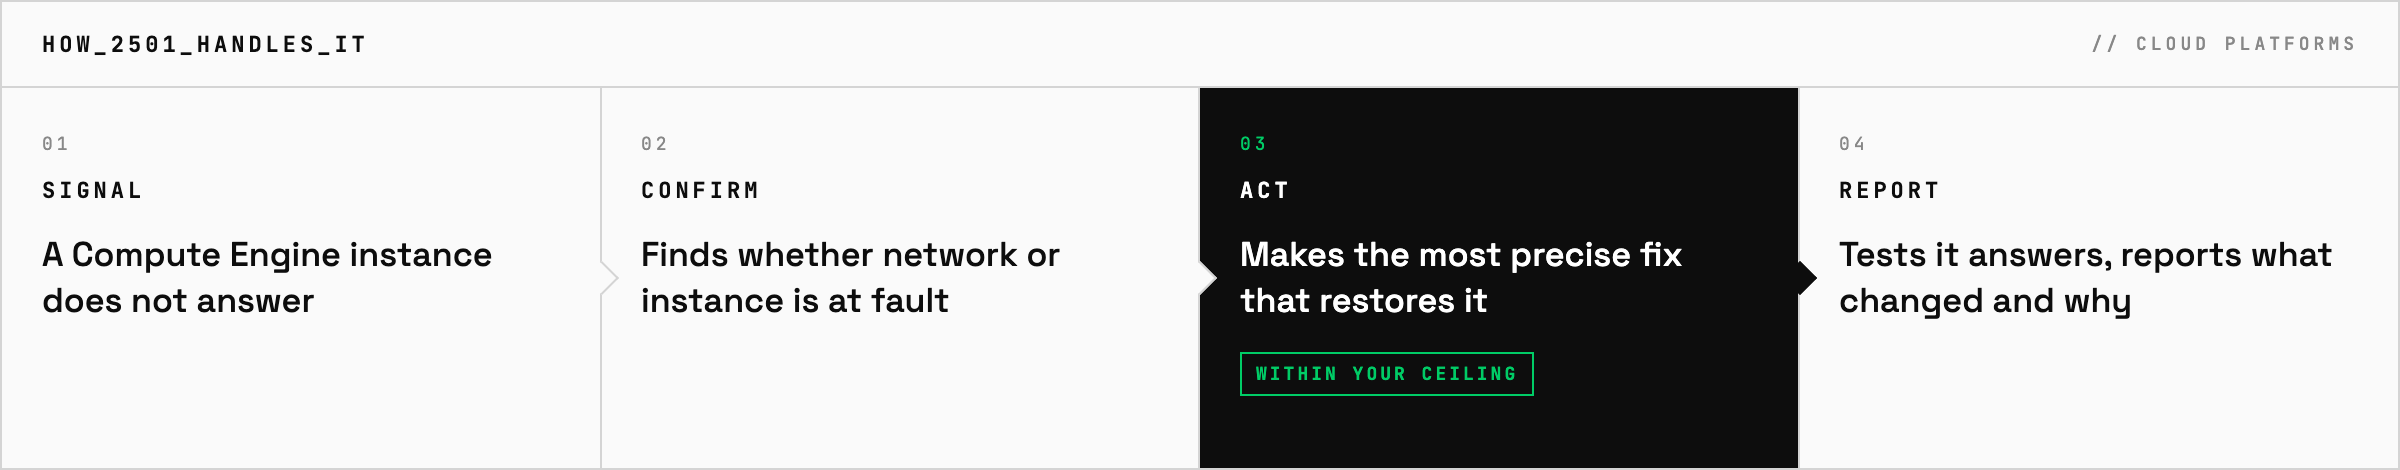
The Google Cloud Central specialty takes the ticket from your ticketing system and works out whether the problem lies in the network or on the instance, confirming the cause before it acts. When it cannot tell which instance a ticket means, it asks a person. Where you allow it, it makes the most precise change that solves the problem, such as restarting a failed service or redeploying a resource, and works on the instance itself when that is where the fix is. It then tests that the instance answers and reports what it changed and why.
Why not just reset the instance? A reset is a hard restart: whatever was running stops without a clean shutdown, and if the cause is in the network, the instance comes back just as unreachable.
Can it diagnose without changing anything? Yes. In investigate-only mode it reports where the connection fails and the fix it recommends, and changes nothing.
> READY_TO_DEPLOY
Book a technical demo and walk through your own environment with the 2501 team.
